Google Launches Gemini 3.8 Live and Extended Thinking for Real-Time Voice and Parallel Reasoning
Google DeepMind has officially unveiled two groundbreaking additions to its flagship frontier model lineup: Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking. Built to transform conversational AI from rigid, turn-based exchanges into fluid, human-like dialogue, the new models introduce native speech-to-speech processing, real-time visual grounding, and simultaneous background reasoning. Alongside the launch, Google expanded its developer voice suite with high-throughput API integrations and competitive production pricing.
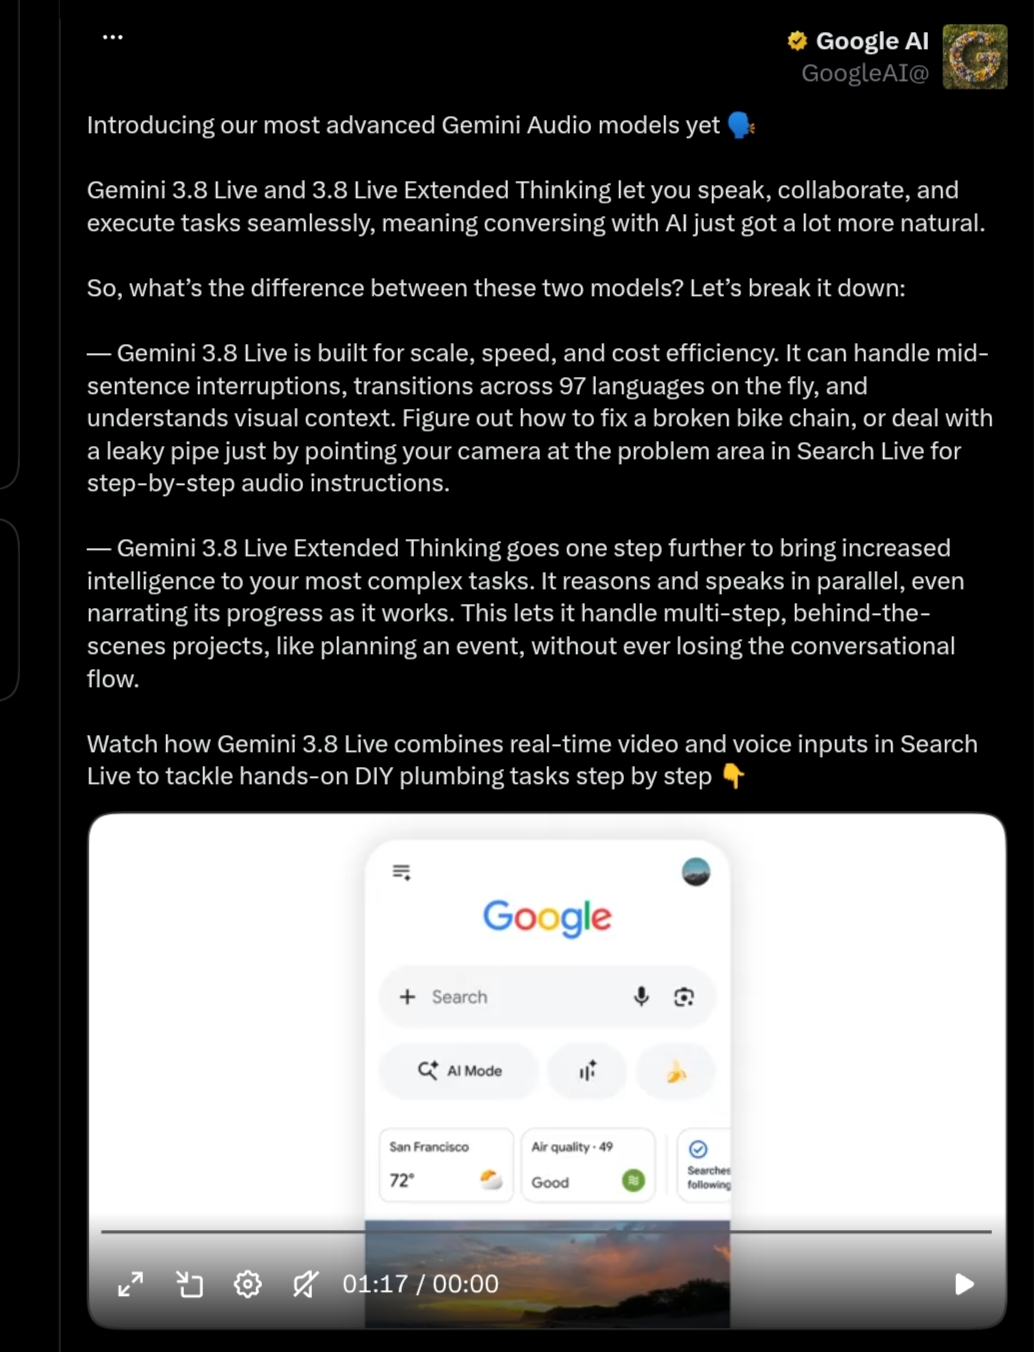
Engineered on the foundation of Gemini 3 Pro, the Gemini 3.8 Audio series is optimized for low-latency, high-volume conversational workflows. By handling multimodal context streams-including continuous live audio, video feeds, and structured data-the models allow individuals, developers, and enterprise teams to collaborate with AI naturally using spoken language alone.
Beyond Cascaded Pipelines: The Native Speech-to-Speech Architecture
Traditional voice assistants have long relied on cascaded pipelines: an Automatic Speech Recognition (ASR) engine transcribes speech into text, a Large Language Model (LLM) generates a textual reply, and a Text-to-Speech (TTS) synthesizer vocalizes the response. This fragmented approach introduced significant latency and stripped away vital paralinguistic nuances, such as emotional inflection, cadence, hesitation, and tone.
In contrast, Gemini 3.8 Live operates as a native end-to-end speech-to-speech architecture. By ingesting and emitting audio directly, the model preserves acoustic subtleties and human context throughout the entire interaction.
“Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking represent our most advanced live dialogue models yet,” noted Tom Ouyang, Principal Engineer at Google DeepMind. “Major upgrades in intelligence and parallel reasoning make them significantly more intuitive to collaborate with, enabling voice-driven execution of complex workflows without conversational disruption.”
Gemini 3.8 Live Extended Thinking: Parallel Reasoning in Real Time
The hallmark innovation of the release is Gemini 3.8 Live Extended Thinking, a model engineered to reason deeply while actively sustaining an ongoing spoken conversation. Rather than freezing into awkward silences when faced with multi-step analytical challenges, the model processes background computations in parallel.
The system utilizes natural verbal cues (such as “Let me look into that…”) to acknowledge complex prompts instantly, providing live progress narration as it navigates intricate reasoning chains. Developers can configure thinking depth parameters to balance computational latency against analytical complexity, making the model versatile for everything from rapid troubleshooting to structured multi-agent coordination.
Benchmark Dominance: Setting New Records Across Speech and Agentic Metrics
Independent performance evaluations position Google’s new models at the forefront of the conversational AI landscape:
- #1 on Speech-to-Speech Quality: Gemini 3.8 Live Extended Thinking secured the top spot on the Artificial Analysis Speech-to-Speech Quality Index with an industry-leading score of 82.6.
- Autonomous Task Execution: The model scored 68.6% on the agentic τ-Voice benchmark and 35.1% on Sierra’s rigorous τ-Voice-banking benchmark for specialized enterprise workflows.
- Acoustic Reasoning: It achieved a remarkable 97.7% on Big Bench Audio, reflecting advanced deductive capabilities directly from sound.
- User Preference & Efficiency: The standard Gemini 3.8 Live ranked #2 overall in the crowdsourced Speech Agent Arena, recognized for its cost efficiency and conversational fluidity.
- Enterprise Workflows: On ServiceNow’s EVA-Bench, the models expanded the Pareto Frontier, successfully balancing operational accuracy with spontaneous conversational quality.
Multimodal Grounding, 97 Languages, and Asynchronous Tool Execution
Gemini 3.8 Live unifies auditory comprehension with near real-time computer vision. In live demonstrations, the model guided employee onboarding by interpreting live video feeds, analyzed dynamic chessboards to recommend strategic moves instantly, and transformed raw paper sketches with voice instructions into fully functional React code components.
Key technical highlights include:
- Broad Multilingual Support: Automatic mid-sentence language detection and fluid transitions across 97 supported languages with consistent regional accents.
- High Alphanumeric Precision: Reliable parsing of complex tracking numbers, alphanumeric verification codes, insurance claims, and technical formulas without transcription hallucinations.
- Asynchronous Function Calling: Background execution of external APIs and database queries while maintaining an uninterrupted voice stream with the user.
- Context Injection (
send_client_content): Real-time streaming of structured client data into the session without triggering artificial conversational turns. - Proactive Audio Mode: Intelligent background listening that responds only when explicitly addressed or when significant auditory/visual events occur.
Developer Ecosystem, Integration Partners, and Disruptive Pricing
Google has made both models accessible to developers via the Gemini Live API and Google AI Studio. The service is priced competitively for scalable production:
- Audio Input: $0.005 per minute (estimated at $3 per 1M tokens)
- Audio Output: $0.018 per minute (estimated at $12 per 1M tokens)
To eliminate media streaming bottlenecks, Google partnered with real-time communications platforms including Agora, Fishjam, LiveKit, LangChain, Pipecat, Vercel, and Vision Agents. These providers handle low-latency WebRTC transport and infrastructure scaling, allowing engineering teams to focus solely on agent logic. Enterprise platforms like Salesforce, Genspark, and Lumeris have already begun embedding Gemini 3.8 Live into enterprise support and clinical operations.
Availability Across Google Workspace, Search Live, and Enterprise Platforms
Google is rolling out the Gemini 3.8 series across consumer, enterprise, and developer touchpoints:
- Developers: Available immediately via the Gemini API, Google AI Studio, and Google Cloud Vertex AI.
- Enterprises: Accessible in private preview through Gemini Enterprise, with an imminent rollout to Gemini Enterprise for Customer Experience.
- End Users & Consumers:
- Gemini 3.8 Live: Integrated directly into Search Live for interactive step-by-step troubleshooting and inside the standalone Gemini mobile app.
- Gemini 3.8 Live Extended Thinking: Rolling out within Google Workspace (Docs Live, Gmail Live, and Keep Live) for Google AI Pro and Ultra subscribers, as well as Workspace commercial customers.
Safety Standards, Frontier Governance, and SynthID Audio Watermarking
Built with an expansive 128K input token context window (supporting audio, video, images, and text) and a 64K token output capacity, the models operate with a knowledge cutoff date of January 2025.
To prevent misinformation and voice cloning abuse, Google DeepMind integrates SynthID into every generated audio stream. This imperceptible acoustic watermark is embedded directly into the waveform, making AI-generated speech verifiable without degrading listening quality.
Under Google’s Frontier Safety Framework, extensive red teaming verified that Gemini 3.8 Live and Extended Thinking do not reach critical Tracked Capability Levels (T/CCLs). Strengthened safeguards against jailbreak attempts and adversarial prompt injections ensure safe deployment across mission-critical enterprise environments.
The Verdict: A New Era for Real-Time Agentic Voice AI
With the release of Gemini 3.8 Live and Extended Thinking, Google DeepMind has successfully bridged the gap between rapid conversational delivery and deep computational reasoning. By removing the latency hurdles of cascaded pipelines and allowing models to think, see, and talk simultaneously, Google establishes a new gold standard for interactive AI agents across global industries.